
Why do A/B testing and statistics questions get asked?
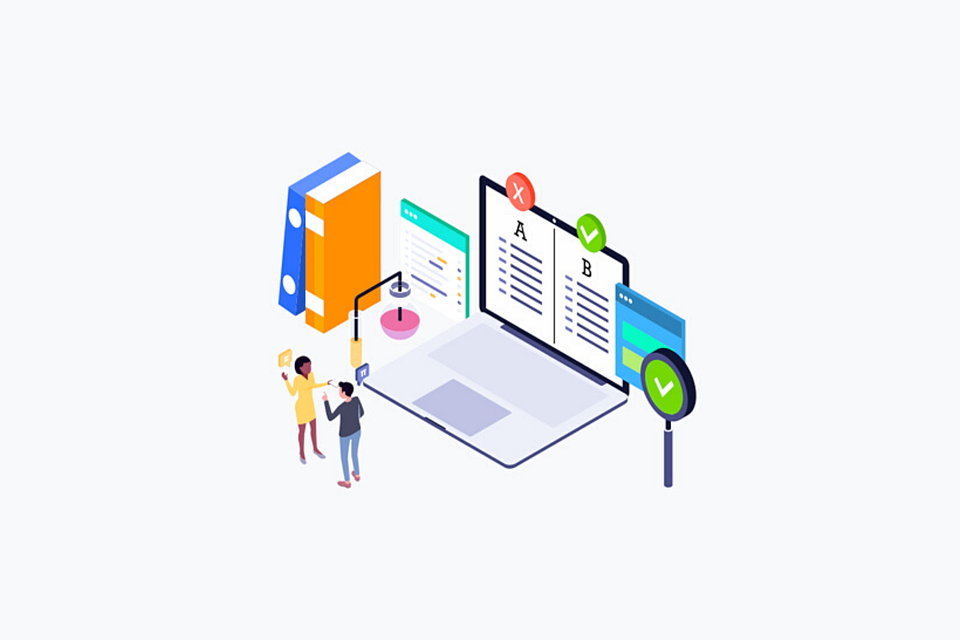
A/B testing, also known as “bucket testing” or “split testing,” comes from a user experience research methodology. At its very core, A/B testing consists of a randomized experiment with two variants that we name A and B. A and B are usually similar, except for one variation that might affect user behavior.
Given the long history of statistics, modern A/B testing is a relatively new phenomenon that originated over 20 years ago as computer usage reached maturity levels. It was simply not possible to A/B test on a large scale with accurate data collection until the Internet made it possible.
There are a few things we have to remember before diving into A/B testing and statistics for interviewing.
Interviewers expect different depths of knowledge on A/B testing and statistics.
Expect various levels of rigor in your interviews among A/B testing and statistics. For example, data scientists at Google are expected to be extremely rigorous about experimental design. Running an experiment there is cheap and traffic is huge, so data scientists often decide what gets tested and how, and interviewers probe the details: sample size, randomization unit, and what can bias a result.
Startups often put less emphasis on experimentation. With a few thousand users, a test may need months to detect a realistic effect, and the team needs to move fast, so interviews there lean toward judgment: when a test is worth running at all, and what to do instead when it is not. Ask your recruiter which kind of role it is, and prepare for that depth.
A/B testing is not a one-trick wonder.
Most A/B tests do not produce a winner. Teams tend to test the ideas they are unsure about, since the ones everyone already agrees on often just get launched, and most of those uncertain ideas turn out to make no measurable difference.
Tests can also mislead. A result can fail to hold up later because of novelty effects, seasonality, a bug in how users were assigned, or plain chance when many metrics are checked at once. Science has the same problem: in a survey of researchers, most said they had failed to reproduce another scientist’s experiment. Knowing these failure modes, and how good experiment design guards against them, is what separates a practical answer from a textbook one.
We can’t apply A/B testing to all situations.
While A/B testing is useful as the answer to most hypothetical questions, it doesn’t work in many cases. In this next section, we’ll dive into how A/B testing should be used, and when it should be avoided.
53%
CompletedYou have 35 sections remaining on this learning path.